Data Engineering: Building the Modern Data Foundation
Data Engineering forms the backbone of modern data-driven enterprises. This crucial field designs, builds, and maintains systems that manage data across its entire lifecycle.
Data engineers turn raw information into valuable business assets. They ensure data is ready for analysis and insight extraction.
What is Data Engineering?
The field of Data Engineering involves building infrastructure for data flow. Engineers manage massive datasets in real-time environments. They provide high-quality information to all business departments. Data engineers make data assets usable. They collaborate with data scientists and analysts closely.
Key Components of Data Engineering
Data Collection and Storage
Engineers start by collecting raw data. They gather it from databases, APIs, and sensors. Next, they design efficient storage solutions. This includes data warehouses and data lakes. Storage must balance speed, scale, and cost-effectiveness.
Data Processing and Pipelines
Data processing transforms raw data into a usable format. This means cleaning, normalizing, and integrating it. Data engineers use tools like Apache Spark for optimization. Data pipelines are automated workflows. These pipelines move data consistently from source to destination. Effective pipeline management ensures data integrity.
Data Quality and Governance
Engineers implement policies to maintain data accuracy. They set up checks and monitor for data anomalies. They enforce compliance with privacy regulations. This ensures secure and reliable data.
Why Effective Data Engineering Matters
Effective Data Engineering is essential for any modern company. It guarantees that data is accurate and ready for use. Reliable data supports machine learning and AI applications. Poor infrastructure creates bottlenecks and inefficiencies. Companies need structured data to gain meaningful insights. It unlocks the full potential of data assets.
Core Responsibilities of a Data Engineer
Data engineers manage data from its creation to its archive. They build platforms for data acquisition. They select optimal storage solutions, like SQL or NoSQL. Engineers set up ETL processes to clean and pre-process raw data. They combine different data streams into one verified system. Data engineers also monitor quality and enforce security rules. They actively optimize queries and workflows for better speed.
[adrotate group=”1″]
Tools and Challenges in Data Engineering
Data engineers leverage powerful database systems. These include MySQL, PostgreSQL, and MongoDB. Data warehousing uses Amazon Redshift or Snowflake. Big Data needs Apache Hadoop and Spark. Data orchestration tools like Airflow manage complexity. Handling massive data volumes is a major challenge. Maintaining high data quality is also complex. Systems must scale quickly with demand. You can Shop Our Products to explore relevant technologies. Security and compliance are continuous top priorities. Data engineers must continually update their technical skills.
Data Engineering vs. Data Science
Data engineering focuses on infrastructure and preparation. Data science focuses on analysis and modeling. Engineers prepare and manage the data stream. Scientists extract insights and build models. Both disciplines are vital for successful data strategy. You can Read Our Blog for more comparisons on these roles.
Conclusion
Data Engineering is the basis for success in data management. It guarantees data accuracy, reliability, and accessibility. This allows businesses to make informed decisions. It helps drive significant growth.
Data warehouse and AI integration: A 2025 Necessity for Business Success
Data warehousing is changing fast. Artificial Intelligence (AI) drives this massive shift. Traditional data warehouses relied on manual, slow reporting. Now, they become dynamic and smart ecosystems. AI helps businesses get real-time insights. It automates data management tasks. It allows seamless scaling.
How AI Reshapes Data Warehousing
AI introduces many advanced capabilities. It automates data ingestion. It powers predictive analytics. It enables self-optimizing storage solutions. Organizations process huge amounts of data faster than ever before. This includes both structured and unstructured data. AI eliminates bottlenecks from old ETL processes. Machine learning models detect anomalies easily. They optimize queries and enhance governance. This ensures accuracy and compliance across all operations.
The Need for Real-Time Insights
Businesses generate much more data today. They rely heavily on this data. The demand for real-time analytics is surging. Organizations need insights fast. They track customer behavior in seconds. They monitor market trends instantly. AI-driven data warehouses meet this high need. They use in-memory computing. They deploy automated indexing. They leverage intelligent caching techniques. AI also enhances scalability significantly. It dynamically allocates resources based on demand. This keeps performance high without huge infrastructure costs. Read Our Blog for more insights on data scaling.
The Competitive Edge of AI Automation
Businesses risk falling behind in 2025. They must adopt AI-driven data warehouses. Competitors already leverage AI for speed and efficiency. AI allows faster decision-making. It improves data accuracy and reduces costs. AI-powered automation decreases manual data engineering tasks. This lets your team focus on innovation. They can pursue strategic initiatives instead. AI-driven quality management ensures reliable data. Accurate information leads to better business outcomes.
[adrotate group=”1″]
Core Benefits of AI-Driven Data Warehouses
AI delivers strong business advantages. These benefits drive growth and efficiency. Organizations gain a significant competitive edge. They make faster decisions across the board. They optimize their operations easily. They ensure data integrity at massive scale.
Accelerated Decision-Making: AI provides instant insights. It predicts future trends accurately. It helps identify critical business opportunities.
Operational Efficiency: Automation speeds up data pipeline processes. Query optimization reduces processing time and costs. AI handles complex data transformations automatically.
Enhanced Data Security: AI detects suspicious patterns instantly. It helps enforce strict security policies. It protects sensitive information effectively.
Seamless Scalability: AI dynamically adjusts resource allocation. It manages growing data volumes easily. It ensures consistent performance under heavy load. Check out our solutions to streamline your operations. Shop Our Products today.
Addressing Implementation Challenges
AI data warehousing offers huge advantages. Yet, businesses face implementation hurdles. They must ensure seamless deployment and top performance. Key obstacles include data integration complexity and cost.
Integration Complexity
Integrating various data sources is difficult. This includes structured and unstructured data. Fragmented ecosystems cause inefficiencies. AI helps bridge these gaps. It standardizes diverse data formats. It ensures consistency across all sources. It eliminates data silos effectively.
Model Accuracy and Bias
AI models detect trends and optimize queries. They can suffer from bias or inaccuracies. Organizations must ensure trustworthy insights. They need continuous validation. They must implement high transparency measures. This minimizes the risk of misleading predictions.
AI-powered data warehousing requires investment. You need cloud infrastructure and AI tools. You must ensure a strong Return on Investment (ROI). Define clear metrics first. Optimize AI resource allocation carefully. This ensures strong financial and operational returns.
The Future: Hyperautomation and Generative AI
The future of data warehousing is exciting. AI will enable self-optimizing systems. Real-time adaptive analytics will become standard. Hyperautomation will refine query execution. Instant insights will flow without human help. Generative AI will automate reporting fully. It will create personalized dashboards. This democratizes data analytics for all business users.
Conclusion: Embrace the AI-Driven Era
AI-powered data warehousing is necessary now. It is not just a concept. It helps businesses stay competitive and agile. Integrating AI accelerates real-time analytics. It enhances security significantly. It drives much smarter decision-making. Embrace these innovations to secure your business future.
[geo_ai_verdict]
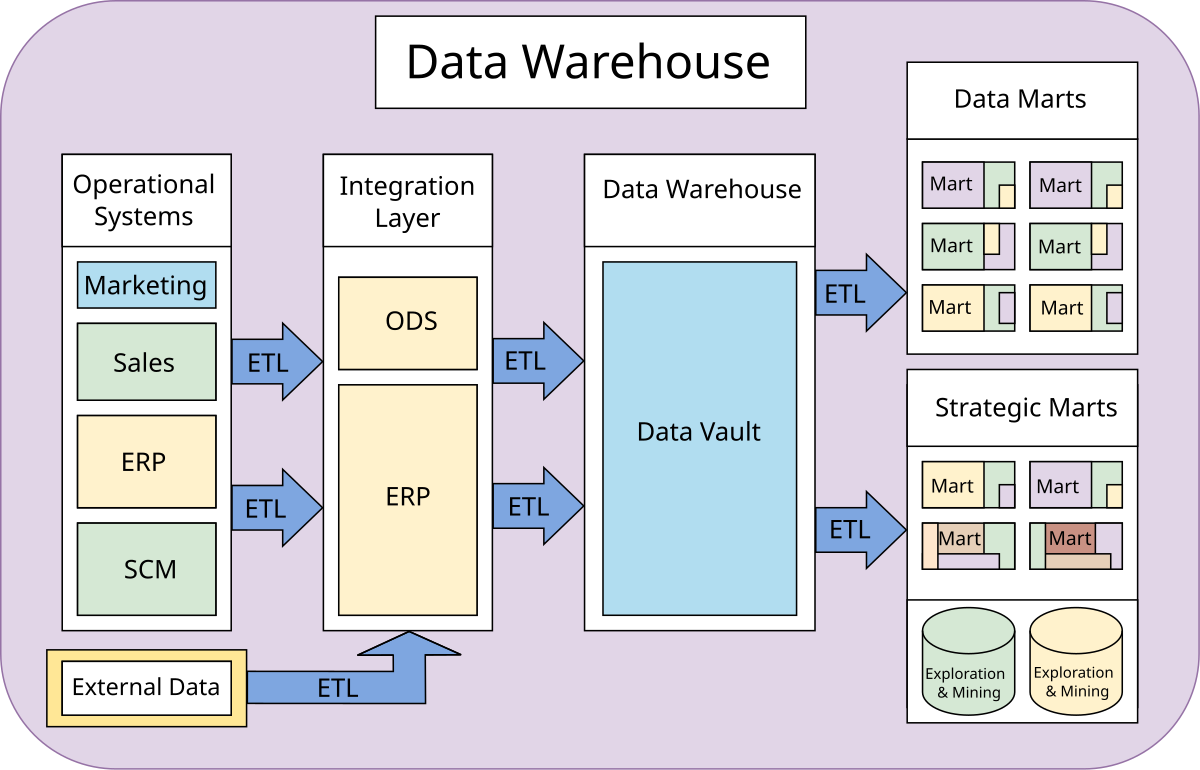
A Data Warehouse (DW) is a vital system in computing. It supports reporting and data analysis. This makes it a core part of business intelligence (BI). DWs act as central storage areas. They integrate data from many different sources. These systems organize current and historical data for optimal analysis. Analysts and managers use DWs. They use the insights generated to make crucial organizational decisions.
How Data Warehouses Handle Data
Data gets uploaded from operational systems, like sales or marketing platforms. The data often moves through an operational data store first. Data cleansing is necessary to ensure high quality before it enters the DW. We primarily use two main methods to build a DW system. These methods are Extract, Transform, Load (ETL) and Extract, Load, Transform (ELT). ETL requires data transformation before loading. ELT loads the raw data directly first. Then it handles all necessary transformations inside the data warehouse itself. This is often done using a staging area within the DW. You can learn more about specialized tools on our website. Shop Our Products now.
Databases for Different Goals
Operational databases focus on speed and data integrity. They use database normalization. This design keeps data accurate. However, one transaction might spread information across many tables. This design allows for very fast updates. Data warehouses, however, optimize for analytical access. They select specific fields instead of loading all data.
[adrotate group=”1″]
Understanding OLAP and OLTP
We use different database management systems for these two types of processing. Online Transaction Processing (OLTP) handles many short online transactions. Examples include INSERTs, UPDATEs, and DELETEs. OLTP emphasizes fast query processing. It maintains detailed and current data. Performance focuses on transactions per second. Online Analytical Processing (OLAP) uses complex queries. These queries involve data aggregations. OLAP systems store aggregated, historical data. They often use multi-dimensional schemas like star schemas. OLAP is excellent for data mining. Response time measures OLAP performance.
Modeling Your Data Warehouse
You have two important approaches for storing DW data: dimensional and normalized.
1. Dimensional Approach
Ralph Kimball proposed the star schema. This approach partitions transaction data into “facts” and “dimensions.” Facts are numeric measurements, like total price paid. Dimensions provide context, such as customer name or order date. This structure makes data easier to understand. It also speeds up data retrieval. However, adding new, unstructured data can be challenging.
2. Normalized Approach (3NF)
Bill Inmon proposed this entity-relational model. Data follows database normalization rules. Normalized tables group into subject areas. Examples include customers or finance. This approach makes adding new information straightforward. However, it involves many tables. Users may find it hard to join data without deep structural knowledge. Both models use joined relational tables. They only differ in their degree of normalization. The best choice depends on your specific business problem. We often publish guides to help you make these choices. Read Our Blog for the latest insights.
A Brief History
The idea of data warehousing began in the late 1980s. IBM researchers Barry Devlin and Paul Murphy developed the “business data warehouse.” They wanted an architectural model for data flowing to decision support environments. Before this, companies wasted money on massive data redundancy. Multiple decision support systems often needed the exact same stored data. Early DW concepts aimed to reduce these high costs. They provided a centralized, efficient way to manage historical business data.
Facts and Aggregations
A fact is a value or measurement within the managed system. Raw facts come directly from the reporting entity. For instance, a cell tower reports channel allocation requests. Aggregated facts, or summaries, roll up raw data. If a city has three towers, you aggregate the requests to the city level. This process helps extract more relevant business information.
Business Intelligence (BI) involves strategies and technology. Businesses use BI for data analysis. It helps manage crucial business information. This data informs key business strategies and operations. Common BI functions include reporting, analytics, and dashboard creation. BI also covers data mining and predictive analytics. These tools process large amounts of data effectively. This data can be structured or unstructured.
How BI Creates Strategic Value
Organizations use BI to find new strategic opportunities. BI helps make big data easy to understand. Finding new opportunities is crucial for growth. Effective strategies based on these insights give businesses a competitive edge. BI supports long-term stability and informs strategic decisions. It ranges from daily operations to high-level strategy planning.
Applications of Business Intelligence
Enterprises use BI to support many business decisions. Operational decisions cover things like product positioning or pricing. Strategic decisions set broad company goals and direction. BI works best when it combines internal and external data. External data comes from the market environment. Internal data includes financial and operational records. Combining this data creates true ‘intelligence.’ This comprehensive view is impossible using only one data source. BI tools help organizations understand new markets. They assess product demand. They also accurately measure marketing campaign effectiveness.
[adrotate group=”1″]
BI History and Evolution
The term “business intelligence” first appeared in 1865. Richard Millar Devens used it then. He described how banker Sir Henry Furnese profited from fast information. Furnese acted quickly on news before his competitors. Devens argued that collecting and acting on information is central to BI. Later, in 1958, IBM’s Hans Peter Luhn used the term. He defined intelligence as “the ability to apprehend the interrelationships of presented facts.”
In 1989, Howard Dresner proposed a broader definition. He called BI an umbrella term. It described methods that improve decisions using fact-based support systems. This modern usage became widespread in the late 1990s. Today, BI uses methodologies, processes, and technologies. They turn raw data into useful information. This enables effective strategic and operational decisions.
BI vs. Related Fields
People often confuse Business Intelligence and Competitive Intelligence. BI primarily analyzes internal, structured data. Competitive Intelligence focuses on competitors and external data. Competitive Intelligence is typically a subset of BI. Some also confuse BI and Business Analytics (BA). Thomas Davenport separates these terms. He says BI includes querying, reporting, and Online Analytical Processing (OLAP). BA is the subset focusing on statistics, prediction, and optimization.
Dealing with Unstructured Data
Business operations create huge amounts of unstructured data. This includes emails, chats, and presentations. More than 85% of all business information exists this way. Managing semi-structured data remains a key challenge. Organizations must accommodate this data when designing BI solutions. We need metadata to improve data searchability. Metadata adds context, such as author or topic summary. Technologies like automatic categorization help generate this metadata.
Generative BI
Generative BI uses generative AI techniques. Large language models are key here. This approach makes data analysis easier for everyone. Users interact with data using natural language queries. This helps generate actionable insights quickly. For example, Microsoft integrated Copilot into Power BI.
Take the Next Step in Data Strategy
Are you ready to optimize your data systems? You can learn more about data management and technology trends when you Read Our Blog. If you need robust solutions now, please Shop Our Products.
Data engineering builds robust data systems. It is a software engineering approach. These systems help collect and use crucial data. People use this data for analysis and data science. This often includes machine learning. Making data usable requires significant computing and storage. It also demands careful data processing.
The History of Data Systems
The term Information Engineering Methodology (IEM) appeared around the 1970s. It described database design. IEM also involved using software for data analysis. Database administrators (DBAs) used these techniques. Systems analysts also adopted them. They needed to understand organizational processing needs. Clive Finkelstein was a key contributor. Many call him the “father” of IEM. He co-authored an important report with James Martin. Finkelstein focused on a business-driven direction. Martin continued a data processing focus.
The Rise of the Data Engineer Role
IT teams generally held all data tools in the early 2000s. Other teams used the data for reporting. Data skillsets rarely overlapped across the business. The internet brought massive data increases in the 2010s. This included huge volume, speed, and variety. The term “big data” described this shift. Companies like Facebook started using “data engineer.” Traditional ETL methods no longer worked. Major firms moved away from old techniques. They created data engineering. This focused on infrastructure, warehousing, and security. Cloud computing drove much of this change. Data became important for sales and marketing teams too.
Processing and Storing Data
High-performance computing is vital for data analysis. Dataflow programming is a popular approach. This represents computation as a directed graph. Nodes are the operations. Edges show the data flow. Apache Spark is a popular example. TensorFlow is specific to deep learning. Newer systems use incremental computing. This makes data processing much more efficient.
We offer the latest tools for data professionals. Please Shop Our Products today!
[adrotate group=”1″]
Data engineers optimize storage systems. They reduce costs through compression and partitioning. The intended usage dictates how you store the data. Structured data often requires online transaction processing (OLTP). In this case, people use databases. Relational databases were originally common. They guarantee ACID transaction correctness. They mainly use SQL queries. Data growth in the 2010s popularized NoSQL databases. They scale horizontally more easily. They trade ACID guarantees for scalability. Newer NewSQL databases try to maintain ACID guarantees. They still allow horizontal scaling.
Data Warehouses and Data Lakes
If you need online analytical processing (OLAP), use data warehouses. Data warehouses enable large-scale data analysis. This includes mining and AI. Data often moves from databases into warehouses. Analysts and data scientists access these warehouses. They use SQL or business intelligence tools. A data lake is a centralized storage spot. It handles huge volumes of secured data. A data lake holds structured and unstructured data. You can build data lakes on-premises. Many use cloud services from Amazon or Google. Unstructured data is often stored simply as files.
Workflow and Modeling
The number of data processes can overwhelm users. Workflow management systems help handle this complexity. Tools like Airflow specify and monitor data tasks. Tasks are often specified as a directed acyclic graph (DAG). Designing data systems involves several parts. This includes architecting platforms and designing stores. Data modeling represents data requirements. A data model organizes business concepts. It shows the relationships and constraints. These models guide communication. They also inform the final database design.
Data Engineer vs. Data Scientist
A data engineer is a software engineer. They build big data ETL pipelines. They manage the data flow organization-wide. This translates data into actionable insights. They focus on production readiness. They worry about formats, resilience, and security. Data engineers usually have a software engineering background. They know languages like Python or Java. They understand architecture and cloud computing.
Data scientists focus on analysis. They know mathematics and algorithms well. They are experts in statistics and machine learning. You can learn more about these roles when you Read Our Blog.
How to Use Python for SEO Automation: A Complete Guide
SEO tasks consume countless hours. Manual work leads to burnout and missed opportunities. Python programming solves these problems. Python transforms repetitive SEO processes into fast, scalable scripts. This guide shows how industry leaders use Python. You will learn to automate keyword research. You will conduct technical audits quickly. Python gives you enterprise-level leverage.
Why Python Dominates SEO
Python is the best choice for SEO automation. Five critical reasons explain this dominance.
1. Easy to Learn, High Impact
Python has a minimal learning curve. Its syntax is very readable. Beginners write functional scripts quickly. The language reads almost like English. You do not need a computer science degree.
2. Powerful, Specialized Libraries
Python includes specialized libraries. These tools solve specific SEO challenges. BeautifulSoup parses HTML for audits. Pandas processes huge keyword spreadsheets. Scrapy crawls entire websites in minutes. You avoid coding complex functions from scratch.
3. Simple API Integration
Major SEO tools offer Python APIs. Google Search Console, Ahrefs, and SEMrush connect easily. One script pulls data from many sources. It combines insights and generates unified reports. Automation merges data seamlessly.
4. Handles Massive Data Volumes
Python handles millions of data points easily. Excel often crashes with large files. Python analyzes crawl data from huge websites. It compares thousands of search queries fast. Tasks that take weeks finish in minutes.
5. Runs Everywhere (Cross-Platform)
Python scripts run on all operating systems. Deploy them on cloud servers. Automated tasks run 24/7. Monitoring competitors happens daily. This capability shifts SEO from reactive to proactive strategy.
Python for Keyword Research
Manual research limits discovery. Python transforms keyword strategy. It replaces guesswork with data precision.
Automated Keyword Expansion
Start with base keywords. Python expands them programmatically. Scripts query the Google Suggest API. They extract “People Also Ask” questions. They mine competitor keyword gaps automatically. This five-minute script replaces 20 hours of manual work. You can also visit our resource page to Shop Our Products for pre-built templates.
Large-Scale Analysis
Python batch-processes long keyword lists. It pulls search volume and CPC data fast. It analyzes 10,000 terms at once. You prioritize action lists instantly. This shows the best opportunities quickly.
Machine Learning Intent Classification
Traditional categorization is slow and inconsistent. Python uses Natural Language Processing (NLP). It automatically classifies user intent. Accuracy reaches 85-90%. Content strategies align with user intent at scale.
[adrotate group=”2″]
Competitive Gap Analysis
Python finds keywords your competitors rank for. It identifies terms you are missing. Scripts analyze top 10 competitors simultaneously. They generate prioritized content lists. Competitive intelligence takes minutes, not days.
Technical SEO Audits
Large websites hide technical issues. Manual audits take weeks and often miss problems. Python automates analysis in hours.
Custom Website Crawlers
Use Python’s Scrapy library. Build crawlers for specific audit needs. Custom crawlers check response codes. They analyze load speeds. They map internal links. They flag technical issues precisely.
Broken Link Detection
Broken links hurt user experience. They waste crawl budget. Python systematically checks every link. It categorizes 404s, 500s, and redirects. It generates fix-priority reports weekly. Catch issues before they impact rankings.
Structured Data Validation
Rich snippets need correct schema markup. Manual validation is impractical on large sites. Python extracts JSON-LD and microdata. It validates against schema.org standards. It ensures correct schema implementation instantly.
Monitoring Core Web Vitals
Core Web Vitals influence Google rankings. Performance metrics often fluctuate. Python integrates with the PageSpeed Insights API. It tests LCP, FID, and CLS across your whole site. Receive alerts when page speeds degrade. Prioritize optimizations using real performance data.
Content Optimization Automation
Content quality requires analysis of many signals. Python handles this analysis perfectly.
TF-IDF for Relevance
TF-IDF shows what keywords top content uses. Python calculates TF-IDF scores across competitors. It identifies missing terms and ideal density. This data-backed strategy replaces subjective content decisions.
Readability Score Calculation
Content must be easy to read. Python calculates Flesch Reading Ease scores. It flags complex pages needing simplification. Batch-analyze thousands of pages fast. This ensures content matches your audience. Read Our Blog for more SEO tips written for maximum readability.
Automated Content Gap Analysis
Scrape competitor content using BeautifulSoup. Extract their headings and topic coverage. Compare this data to your own pages. Python identifies missing topics immediately. Ensure your content surpasses competitor comprehensiveness.
Internal Linking Detection
Strong internal linking distributes authority. It helps search engines understand your site. Python suggests linking opportunities. It flags orphan pages without links. It automates finding connections that manual reading often misses.
Conclusion
Python empowers you to scale SEO efforts. It eliminates repetitive work. Automation drives efficiency and accuracy. Start transforming your SEO strategy today.
How AI and Machine Learning Transform Data Warehouse Efficiency and Insights
The modern enterprise runs on data, and the data warehouse (DW) is the central engine powering business intelligence (BI) and analytics. However, as data volumes explode and complexity increases, traditional data warehouse management can become cumbersome. The key to unlocking speed, efficiency, and higher-quality insights lies in the strategic integration of Artificial Intelligence (AI) and Machine Learning (ML).
The Data Warehouse: The Single Source of Truth
A data warehouse is fundamentally a central repository designed to store data pulled from disparate operational sources, such as relational databases and transactional systems. Unlike raw data storage, a DW organizes this information based on predefined schemas, making the data structured and ready for rapid analysis, reporting, visualizations, and ad hoc querying by BI applications.
Functioning as an organization’s single source of truth, the data warehouse gathers input from every department, creating a comprehensive and architecturally sound database. This centralized structure not only simplifies access but also provides the massive, high-quality datasets that AI and ML applications require to function optimally.
Understanding the Difference: AI vs. Machine Learning
While often used interchangeably, AI and ML have distinct roles:
Artificial Intelligence (AI): AI enables machines to simulate human logic to solve problems and make decisions based on data. It excels at automating complex or repetitive tasks, optimizing processes, and overseeing detail-oriented functions that traditionally require explicit programming instructions.
Machine Learning (ML): ML is a subset of AI focused on learning. ML algorithms analyze vast datasets, learn from the patterns discovered, and incrementally improve their accuracy over time without being explicitly programmed for every decision. This learning capability makes ML ideal for predictive analytics, forecasting, and data classification.
5 Ways AI and ML Supercharge Data Warehouse Operations
Integrating AI and ML into a data warehouse enhances core functions, improving both processing power and operational oversight.
1. Automation of Data Management Tasks
AI is perfect for automating the tedious, repetitive, and intensive data tasks that consume valuable human resources:
Data Integration: Ensuring smooth, continuous connections between data sources and the warehouse pipeline.
Performance Monitoring: Automatically checking for broken connections and ensuring all critical processes are active and functioning as expected.
Data Cleansing and Validation: Verifying data elements are accurate, complete, and consistent.
By automating these crucial processes, IT administrators and data teams are freed to concentrate on higher-value strategic responsibilities.
2. Enhanced Data Processing and Query Optimization
Both AI and ML excel at parsing large volumes of data quickly. AI can be programmed to handle simple, common queries swiftly, while ML algorithms can be trained to manage highly complex queries. This combined approach significantly improves the speed of data processing, allowing the warehouse to handle larger and more intricate datasets.
Furthermore, ML can analyze historical query performance to identify patterns and bottlenecks—for instance, noting that a particular data task repeatedly slows down an entire process. Uncovering these inefficiencies leads to targeted optimizations that dramatically boost query performance.
3. Intelligent Schema and Architecture Management
Data schema in an enterprise environment can become incredibly complex. AI can manage schema issues proactively by flagging or mitigating errors that could cause massive downstream problems. ML takes this further by analyzing schema usage patterns to determine and recommend the most efficient strategies and architectures, resulting in a leaner, more organized, and faster data warehouse.
4. Superior Predictive Analytics and Anomaly Detection
ML’s powerful ability to analyze patterns enables it to identify trends in stored data that human analysts might overlook. Using historical data trends, ML can forecast outcomes, giving the organization a competitive edge by predicting customer demand, market shifts, or potential downtime issues. This proactive approach helps the organization stay one step ahead.
5. Democratization of Business Intelligence
AI and ML not only improve backend efficiency but also broaden accessibility. They can improve data quality and query accuracy, making BI applications easier to use for non-technical users. For example, a user lacking deep data literacy skills can simply input a natural language command and receive insights presented in easy-to-understand formats, such as simplified visualizations. This fosters better-aligned decision-making across the entire enterprise.
The Outcome: A Future-Proof Data Strategy
A data warehouse augmented with AI and ML is not just faster and more efficient; it is future-proof. It scales more quickly and easily alongside organizational growth and evolving technological demands. By optimizing data storage (e.g., automatically identifying and deleting redundant data) and automating ETL (Extraction, Transformation, Loading) processes, AI and ML provide cost-effective operations, freeing up data teams to focus on core business responsibilities that drive the bottom line.
The Definitive Guide to Data Warehousing: Architecture, Evolution, and Implementation
The modern enterprise generates massive amounts of data from diverse sources—from transactional systems and CRMs to IoT devices and social media. To make sense of this volume and extract valuable business insights, organizations rely on a foundational technology: the data warehouse (DW).
What is a Data Warehouse?
A data warehouse is a core component of business intelligence, designed to ingest and store large volumes of historical data from a wide range of source systems. Unlike transactional databases, data warehouses are specifically configured and optimized for rapid, complex analytical queries rather than high-volume transaction processing.
The concept originated in the 1980s as a solution to integrate disparate operational data into a consistent format suitable for analysis. While traditionally optimized for structured data, the growing demand for analyzing massive volumes of raw, unstructured data has led to the evolution of flexible alternatives, such as cloud-native data warehouses and data lakehouses.
The Traditional Three-Tier Data Warehouse Architecture
Data warehouses commonly utilize a three-tier architecture specifically designed to transform raw data into actionable information:
Tier 1: Data Integration and Storage
Data flows from multiple source systems (like operational databases or transactional platforms) into the data warehouse server where it is stored. This process involves sophisticated data integration methodologies:
ETL (Extract, Transform, Load): Traditionally, data moves through an ETL process, where automation is used to clean, organize, and standardize data before loading it into the warehouse. Because traditional data warehouses primarily store structured data, transformation is upfront.
ELT (Extract, Load, Transform): Modern warehouses, especially those leveraging cloud computing, often use ELT. Data is loaded into the warehouse first, and transformation occurs afterward. This method is highly efficient for handling massive data volumes.
Tier 2: The Analytical Engine (OLAP)
This tier contains the analytics engine, typically powered by an Online Analytical Processing (OLAP) system. While traditional databases are not optimized for multidimensional queries (e.g., sales data across location, time, and product), OLAP systems are built for high-speed, complex analysis on vast volumes of data.
OLAP utilizes “cubes”—array-based multidimensional data structures—to enable faster, flexible analysis across dimensions, making them essential for financial analysis, budgeting, forecasting, and data mining. This contrasts sharply with Online Transaction Processing (OLTP) systems, which focus on capturing and updating real-time transactions.
Tier 3: The Front-End User Interface
The final layer provides the interface for users to interact with the data. This includes self-service business intelligence (BI) tools, reporting mechanisms, dashboards, and ad hoc data analysis tools. These tools empower business users to generate reports based on historical data, visualize trends, and identify bottlenecks without requiring deep technical data engineering expertise.
Evolution: From On-Premises to Cloud and Hybrid Models
Data warehousing has moved beyond exclusively on-premises deployments. Historically, DWs were hosted on-premises using expensive, dedicated hardware organized in Massively Parallel Processing (MPP) or Symmetric Multiprocessing (SMP) architectures. While these required significant investment, they offered robust security suitable for regulated industries.
Today, the majority of new data warehouses are cloud-native, offering substantial benefits:
Scalability: Data storage capacity can reach petabyte scale, with highly scalable compute and storage resources.
Cost-Efficiency: Utilizing pay-as-you-go pricing eliminates the need for large upfront hardware investment.
Managed Service: Often delivered as fully managed Software as a Service (SaaS), cloud DWs reduce infrastructure management overhead, allowing organizations to focus purely on analytics.
Some organizations adopt a hybrid model, combining the agility of the cloud with the strict control required for sensitive workloads that must remain on-premises.
How Data is Organized: Common Schema Types
Schemas define how data is logically organized within the warehouse. Dimensional data models are used to optimize data retrieval speeds in OLAP systems. These schemas consist of fact tables (containing measurements) and dimension tables (containing descriptive attributes).
Three common schema structures exist:
Star Schema: The simplest and most common structure, featuring a single, central fact table surrounded directly by dimension tables. It offers users the fastest querying speeds.
Snowflake Schema: Features a central fact table connected to normalized dimension tables, which may branch out further to other dimension tables. This complexity reduces data redundancy but typically results in slower query performance compared to the star schema.
Galaxy Schema (Fact Constellation): Best suited for highly complex data warehouses, this schema contains multiple star schemas that share normalized dimension tables. While comprehensive, performance may be lower.
Key Components of a Data Warehouse System
A data warehouse is supported by several integrated components:
Data Layer (Central Database): The heart of the warehouse where integrated data from various sources is stored, typically supported by an RDBMS or a cloud data warehouse platform.
Metadata Management: Metadata—data about data—describes stored information (e.g., table structure, creation date) and is crucial for searchability, usability, and effective data governance.
The Sandbox: A walled-off testing environment containing a copy of production data. This allows data analysts and scientists to experiment with new analytical techniques without impacting live operations.
Access Tools and APIs: Application programming interfaces (APIs) facilitate integration with operational systems and access to advanced analytics and visualization tools (like Tableau or Qlik) that provide the user-friendly front end.
Types of Data Warehouses
Data warehousing systems can be structured in several ways based on scope and purpose:
Enterprise Data Warehouse (EDW): A centralized information repository serving the entire organization, containing historical data across all subject areas.
Operational Data Store (ODS): Contains the most recent snapshot of operational data, updated frequently to enable quick, near-real-time access for daily operational decision-making. An ODS can also serve as a source for the EDW.
Data Mart: A subset of an EDW or other data sources, tailored to a specific business line or department (e.g., a marketing data mart). Data marts provide focused insights without requiring users to navigate the broader enterprise dataset.
Data Warehouse vs. Data Lake vs. Data Lakehouse
It is important to differentiate the data warehouse from related concepts:
Database: Optimized for automated data capture and fast transaction processing for a specific application.
Data Warehouse: Stores data from multiple applications, optimized for predictive analytics and advanced analysis on structured data using predefined schemas (schema-on-write).
Data Lake: A low-cost solution for massive volumes of raw, unstructured, and semi-structured data (IoT logs, videos). It uses a schema-on-read approach and typically does not clean or normalize data upfront.
Data Lakehouse: Represents a modern architectural merge, combining the low-cost flexibility and scale of a data lake with the high performance, structure, and governance features of a data warehouse. Lakehouses accelerate processing for diverse data types, supporting advanced AI and machine learning workloads.
The Value Proposition: Quality, Integrity, and Insight
By preparing incoming data through robust ETL/ELT processes—including cleansing, standardization, and deduplication—data warehouses ensure high data quality and integrity. Integrating this high-quality data into a single, reliable store creates a comprehensive single source of truth, effectively eliminating data silos and enabling self-service analytics that drive informed business decisions.
The Power of Business Intelligence (BI): Transforming Data into Strategic Decisions
In today’s hyper-competitive landscape, data is the most valuable resource. But raw data alone holds little power. Business Intelligence (BI) provides the necessary framework—a combination of technology, processes, and analysis—to transform vast volumes of organizational data into actionable insights that inform every business strategy and operational decision.
What Exactly is Business Intelligence?
Business intelligence (BI) encompasses the technological processes used for collecting, managing, and analyzing historical and current organizational data. The primary goal is to yield clear, meaningful insights that enable strategic decision-making.
BI tools allow business users to access and analyze diverse data types—whether historical, current, internal, third-party, or even unstructured data like social media feeds. BI systems examine this information to help organizations understand how they are currently performing and determine their most optimal next steps.
As industry experts note, BI doesn’t explicitly tell users what to do, nor is it just about report generation. Instead, BI offers a robust, data-driven methodology for examining trends and deriving insights that are crucial for:
Improving business decisions.
Identifying operational problems or inefficiencies.
Spotting emerging market trends.
Finding new revenue streams and business opportunities.
BI vs. Business Analytics: Understanding the Difference
While often used interchangeably, BI and Business Analytics (BA) serve distinct purposes within the data ecosystem:
Business Intelligence (BI) is fundamentally descriptive. It focuses on what has happened—answering questions like: “How many new customers did we acquire last month?” or “Was our average order size up or down?” BI provides the current factual foundation for decision-making.
Business Analytics (BA) is typically a subset of BI and is prescriptive and forward-looking. BA leverages the insights provided by BI to predict future outcomes and suggest optimal strategies. For example, BA might predict: “If we increase advertising spending in this segment, which strategies would yield the highest return?”
BI provides the historical and current context; BA provides the predictive foresight.
The Core Components of a BI System
Traditional BI platforms rely on a robust infrastructure to centralize and analyze data:
Data Warehouses: These systems aggregate data from multiple disparate sources into one central repository. They serve as the baseline for BI reporting and data analytics, ensuring data consistency and accessibility.
Online Analytical Processing (OLAP): Often integrated into data warehouses, OLAP engines support multidimensional queries, allowing users to quickly analyze data across various dimensions (e.g., “Compare sales in the eastern region vs. western region, year-over-year”). OLAP facilitates complex calculations and data discovery.
Data Lakehouses: Representing the evolution of data management, lakehouses aim to combine the structure and governance of data warehouses with the flexibility and scale of data lakes, offering a highly versatile solution for modern BI needs.
Dashboards and Reporting: BI presents results to the user primarily through easily digestible formats like reports, charts, and maps, often compiled into centralized, interactive dashboards.
The concept of using market intelligence to gain an advantage is not new. The term “business intelligence” was first recorded in 1865. However, the modern technological foundation began to take shape much later:
1958: IBM computer scientist Hans Peter Luhn explored using technology to gather BI, laying the groundwork for early analytics platforms.
1960s & 70s: The rise of Decision Support Systems (DSS) and data management systems began storing and organizing growing data volumes.
1990s: BI gained popularity, though early technology was often complex, requiring extensive IT support and specialized training, which led to slower report generation.
Why a Data-Driven Culture Matters
Installing a new BI software package is only half the battle. True business advantage comes from adopting a data-driven culture. BI is as much a mindset as it is technology. When organizations embrace a complete set of approaches, processes, and digital tools—accelerated by Artificial Intelligence (AI)—they empower decision-makers across all functions (from marketing and HR to finance and supply chain) to access flexible, self-service insights.
How Business Intelligence Drives Value Across the Enterprise
BI adds measurable value across nearly every organizational function and industry:
Sales and Marketing: Unifying data on promotions, pricing, sales, and customer actions allows teams to refine segmentation, plan targeted campaigns, and forecast outcomes.
Finance and Banking: Financial firms use combined customer histories and market conditions to determine current organizational health, manage risks, and predict future financial success.
Healthcare: BI streamlines internal operations, tracks inventories, and provides rapid answers to pressing patient or operational questions.
Customer Service: Agents can quickly access unified customer information and product details to resolve concerns faster and improve customer experience.
Supply Chain: Global data visibility on a Single Pane of Glass (SPOG) speeds the movement of goods and identifies bottlenecks and inefficiencies worldwide.
Security and Compliance: Centralized data simplifies reporting for regulatory compliance and helps pinpoint the root causes of security issues.
The Future of BI: Self-Service, AI, and Cloud Platforms
Recent advancements are rapidly evolving the BI landscape:
Self-Service BI: Modern systems focus on empowering non-technical users with self-service applications, allowing multiple teams to run their own analysis.
AI and Machine Learning Integration: The integration of AI algorithms is streamlining complicated analysis tasks and accelerating the ability to gain deeper insights.
Cloud-Based Solutions: Modern BI solutions predominantly reside on cloud platforms, extending their reach globally and facilitating consumer insights drawn from big data.
User-Friendly Interfaces: Features like natural language queries and low-code/no-code development capabilities are emerging, enabling users to create customized reporting tools.
Business intelligence is indispensable for any organization seeking to plan, forecast, and proactively shape future outcomes in a data-driven world.
Building Your First End-to-End Batch Data Engineering Project
Are you a data analyst, student, or scientist looking to pivot into data engineering? Finding a comprehensive starter project that mirrors real-world complexity is often the biggest hurdle. This tutorial walks you through building a complete, end-to-end batch data pipeline designed to simulate an actual production environment, perfect for gaining hands-on experience and preparing for job interviews.
The Business Problem: User Behavior Metrics
Imagine you work for a user behavior analytics company. Your task is to build a robust data pipeline that ingests raw user data and populates a critical OLAP table: user_behavior_metric. This final table is consumed by analysts, dashboards, and other downstream applications.
Core Technologies for Our Pipeline
To execute this complex workflow efficiently, we utilize a powerful open-source stack:
Apache Airflow: For defining, scheduling, and monitoring the data workflow (DAGs).
Apache Spark: Essential for large-scale data processing and machine learning tasks, such as classifying user reviews.
DuckDB: Used for fast, in-process analytical querying via SQL, generating metrics efficiently.
Minio: An open-source object storage solution that acts as an S3 compatible storage layer (OSS S3).
For simplicity, these services are bundled and managed via containerization, allowing you to run the entire project quickly using GitHub Codespaces or locally.
The user_behavior_metric data is derived from two primary datasets, processed through the following stages:
1. Extraction
Data extraction from source systems is handled efficiently using Airflow’s native operators. This stage ensures reliable fetching of raw data before processing begins.
2. Transformation and Metrics Generation
This is where the heavy lifting occurs. We leverage Spark for computationally intensive tasks, specifically implementing a naive Spark ML model for text classification (e.g., classifying user reviews as positive or negative). Calculated metrics, often generated using SQL executed via DuckDB, are then stored in a staging location (e.g., /opt/airflow/data/behaviour_metrics.csv).
3. Visualization and Dashboarding
The final stage involves presenting the processed data to consumers. We use quarto, a powerful tool that allows us to write Python code to generate dynamic HTML dashboards. Airflow’s BashOperator is utilized to trigger the dashboard creation, providing immediate insight into the newly calculated metrics.
Advanced Data Engineering Design Considerations
A successful project goes beyond just running the code. It requires careful design to handle failures, scale, and maintain data quality. After successfully running the user_analytics_dag, consider these critical real-world concepts:
Idempotent Data Pipelines
A core best practice is ensuring every task is idempotent. If a task fails and is re-run, the output should remain consistent. Review your pipeline—can you spot any tasks that might violate this principle?
Monitoring and Alerting
While the Airflow and Spark UIs offer basic monitoring, a production environment requires dedicated alerting for task failures, data quality issues, or hanging processes. Systems like Datadog, CloudWatch, or New Relic are commonly integrated here.
Data Quality Control
We did not implement data quality checks initially. In production, setting up checks (e.g., count validation, standard deviation checks) before loading the final table is crucial. Frameworks like great_expectations or lightweight solutions such as cuallee can enforce quality standards.
Concurrency and Backfills
If you need to re-run the pipeline for past periods (backfilling), concurrent execution is vital. However, review your DAG dependencies; even with appropriate concurrency settings, a blocking task might severely limit performance. Understanding how to manage backfills efficiently (rerunning only parts of the DAG versus the whole) is key to optimization.
Scaling for Growth
How would this architecture handle a 10x or 1000x increase in data volume? Scaling often requires moving beyond single-container setups and optimizing Spark configurations or shifting storage paradigms.
This project provides a comprehensive foundation. By tackling these design considerations, you transform a basic tutorial into a production-ready demonstration of your data engineering skills.